← All Notes
AI Engineering
vLLM: When You Outgrow One Request at a Time
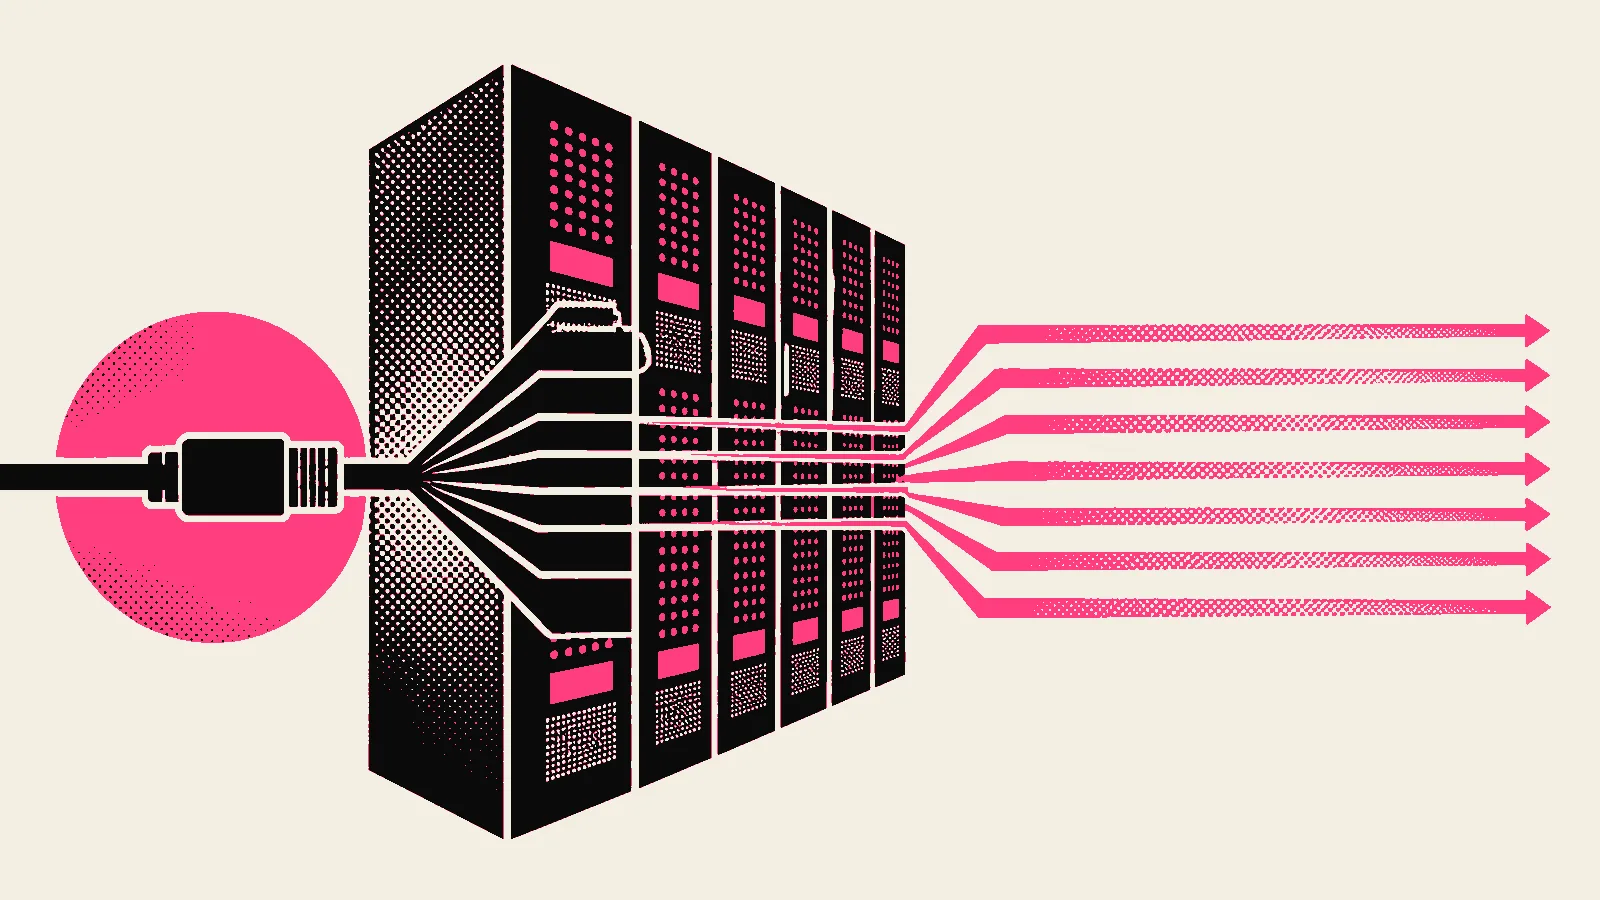
Continuous batching and paged attention are why a serving stack handles fifty concurrent users on hardware that choked on five.
Need this built properly?
I build secure, fast, bilingual platforms for clients across Egypt, Saudi Arabia, the UAE and Kuwait.